Jev TypeSafe · jev-latest
- Text cases
- —
- Image cases
- Text only
- Typical time
- —
- Sure of the right answer
- —
Two live benchmarks from Labs. Decision models answer typed questions with probabilities, scored against known answers. Light assistants prepare the same operational briefs, including a hotel room that has been repaired but not yet inspected. Nothing is filled in before you run it.
01 · Decision models
TypeSafe’s Jev and OpenAI’s Decisions API both answer typed questions (yes or no, a choice, a score) with probabilities rather than prose. Here they answer the same everyday decisions, scored against known answers. Image cases go to the Decisions API only: Jev reads text and JSON.
Why probabilities matterJev TypeSafe · jev-latest
Decisions API OpenAI · gpt-6-luna
Not run yet.
12 cases, 35 questions, live. Each model is timed from our server, so the times include the network. One run is a small sample: a demonstration, not a leaderboard.
Email from Priya at Harper & Co: “Order 4821 was meant to arrive Friday for our shop opening on Saturday. Tracking hasn’t moved since Tuesday. Can you confirm it’ll be here Friday? If not, we need to make other arrangements today.” Order system: order 4821, supplier status “held at depot” since Tuesday, no new delivery date.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Is the customer asking for a delivery commitment? | Yes | … | … |
| What should happen next? | Prepare a summary for the account owner to decide what can be promised | … | … |
| How urgent is this? | Today (2.0) | … | … |
Supplier email: “PO 7710: 120 of the 200 units ship Thursday. Balance to follow, date TBC.” ERP: PO 7710, 200 rolls of 50mm packing tape, due Thursday. Three customer orders depend on it.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Does the update change what was agreed on the purchase order? | Yes | … | … |
| Is a delivery date given for the remaining units? | No | … | … |
| What should happen next? | Ask the supplier for the missing date and keep the order open | … | … |
Expense claim: hotel, 2 nights in Manchester, £412 in total. Receipt attached. Policy: hotels up to £150 a night are approved automatically; anything above needs the budget holder.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Is the claim within the automatic approval limit? | No | … | … |
| What should happen to the claim? | Send to the budget holder to approve | … | … |
Year-end checklist, Riverside Bakery Ltd. Requested 3 February: bank statements (received 10 February), sales invoices (received 10 February), payroll summary (not received), VAT returns (received 12 February). Reminders sent 20 February and 27 February. Filing deadline 31 March. Today is 6 March. Practice rule: after two reminders with no response, the partner phones the client.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Is anything still outstanding? | Yes | … | … |
| Which item is outstanding? | Payroll summary | … | … |
| What is the right next step? | The partner phones the client | … | … |
Web form: “Hi, water is coming through the ceiling in the back bedroom when it rains. I think a few tiles have slipped. Semi-detached in Dudley. Can someone look this week? Sam, 07700 900123” Business rule: a quote needs the full address, the job type and a contact number.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| What type of job is this? | A repair to an existing roof | … | … |
| Does the enquiry include a contact number? | Yes | … | … |
| Does the enquiry include everything needed to quote? | No | … | … |
Order from Fenwick Florists: 40 boxes of 12-inch cellophane at £3.20 a box, delivery Wednesday. Stock: 26 boxes. Price list: £3.20 a box. Their usual order: 30 to 40 boxes.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Can the order be filled in full from stock? | No | … | … |
| Does the price match the price list? | Yes | … | … |
| What should happen next? | Flag the shortfall to a person before confirming | … | … |
Customer message: “The engineer left this morning and the gas smell is worse than before he came. We’ve opened the windows and turned it off at the meter. Please send someone.”
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| How urgent is this? | Immediately (3.0) | … | … |
| Does the message describe a possible safety risk? | Yes | … | … |
| Where should it go? | Pass to the emergency engineer now | … | … |
Return request: “I bought the walking boots on 2 August and have worn them twice. The sole is coming away. Can I have a refund?” Policy: unused items can be refunded within 30 days; faulty items are repaired, replaced or refunded within 6 months. Today is 7 October.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Is the purchase within 30 days? | No | … | … |
| Does the customer describe a fault? | Yes | … | … |
| Which policy applies? | Treat as faulty: repair, replace or refund | … | … |
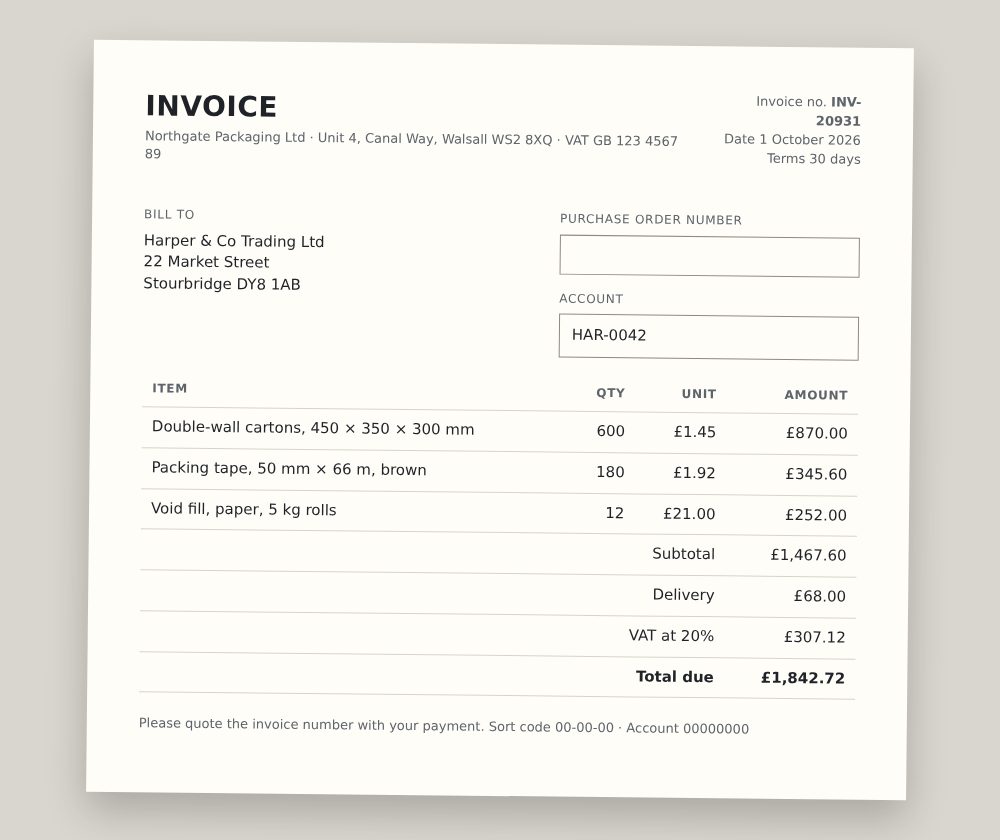 Open full size
This invoice arrived in the accounts inbox. Rule: invoices are only paid against a purchase order.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Does the invoice show a purchase order number? | No | Text only | … |
| What is the invoice total? | £1,000 to £5,000 | Text only | … |
| What should happen next? | Ask the supplier for the purchase order number | Text only | … |
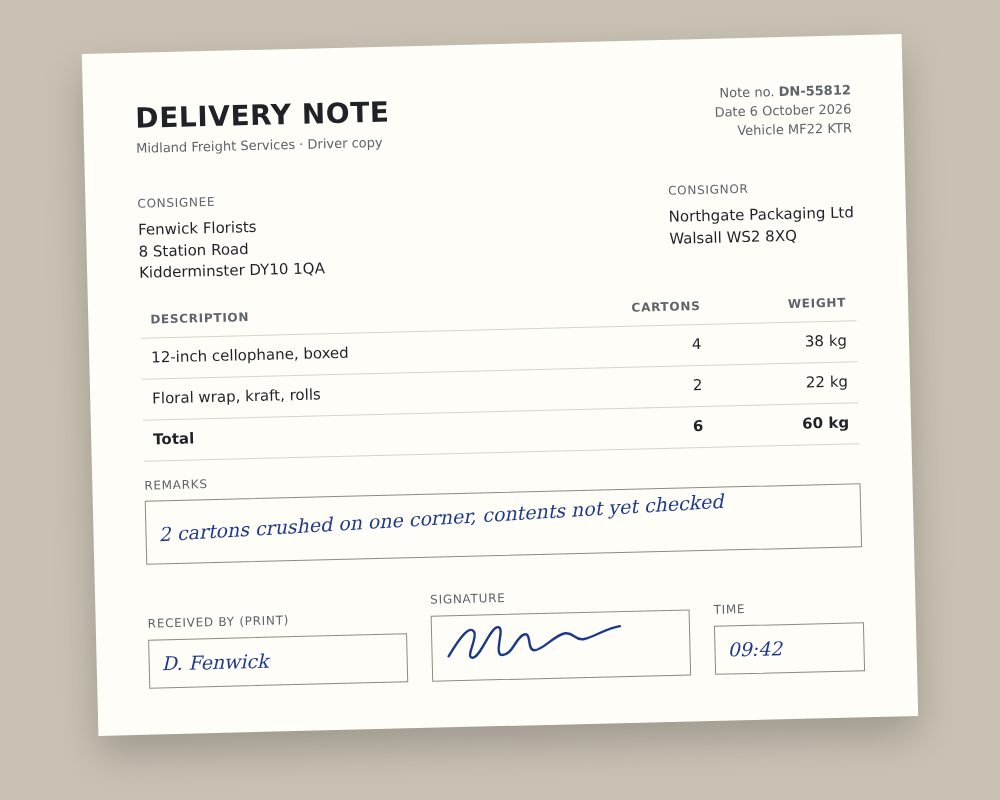 Open full size
A driver’s delivery note, photographed at goods in.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Has the delivery note been signed? | Yes | Text only | … |
| Does the note record any damage? | Yes | Text only | … |
| What should happen next? | Raise a damage claim with the carrier | Text only | … |
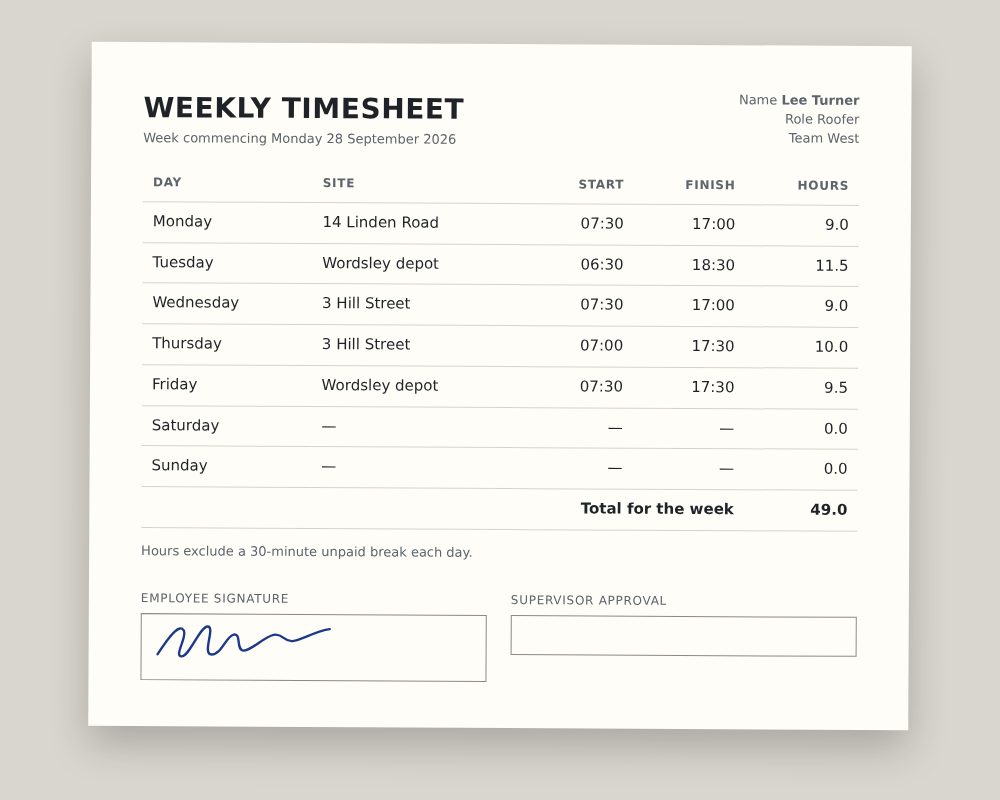 Open full size
A weekly timesheet. Rule: any week over 48 hours, or any day over 11 hours, goes to a supervisor.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| Does any single day exceed 11 hours? | Yes | Text only | … |
| Is the weekly total over 48 hours? | Yes | Text only | … |
| What should happen to it? | Send to a supervisor | Text only | … |
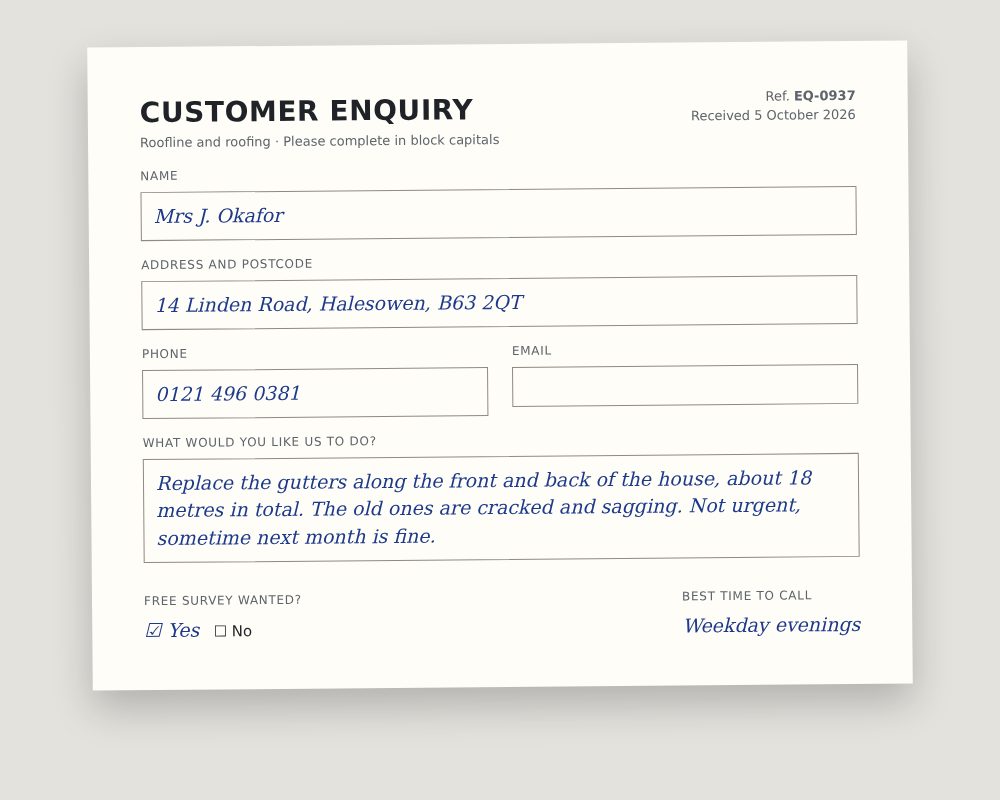 Open full size
A paper enquiry form, scanned. A quote needs the full address, the job type and a contact number.
| Question | Right answer | Jev | Decisions API |
|---|---|---|---|
| What type of job is this? | Replacing a whole roof or roofline | Text only | … |
| Does the form include everything needed to quote? | Yes | Text only | … |
| How urgent is this? | Routine (0.0) | Text only | … |
Any text, and an image if you like. Jev answers from the text; the Decisions API sees the text and the image.
Jev TypeSafe · jev-latest
The answer appears here.
Decisions API OpenAI · gpt-6-luna
The answer appears here.
02 · Operational assistants
OpenAI’s GPT-6 Luna and Anthropic’s Haiku 5.5 prepare summaries, next steps and draft replies from the same facts. It opens on the hotel room: the shower is fixed, but housekeeping hasn’t inspected it, so it isn’t ready to sell. Six synthetic cases, no scores until you run them.
No runs yet. Every result below comes from a live request.
Facilities · Synthetic case
Prepare a handover for housekeeping. Distinguish completed maintenance from permission to return the room to service.
The shower repair and leak test are complete. Housekeeping has not inspected the room. Prepare the handover only; do not update its availability.
Expected route: Prepare for review. Reference: WO-58213. Required missing context: none. Selected facts must match their sources. Actions stay with a person. The models do not receive these expected answers.
OpenAI
GPT-6 Luna · reasoning none
Run a case to see the response, rule checks and measured time.
Anthropic
Haiku 5.5 · effort low
Run a case to see the response, rule checks and measured time.
Rule checks cover the structured response, not every claim in its prose. Time includes the provider request; tokens are reported by each provider. Synthetic cases do not establish performance in your business. Both providers process these examples when you run them. Privacy
03 · Method
Every decision case has an agreed right answer, and every operational brief has checks for its route, reference, facts, missing context and who may act. The models never see them.
Both sides of a comparison get the same case, the same source facts and the same output budget. Image cases go to the Decisions API only, because Jev reads text and JSON.
Haiku 5.5 runs at effort low and GPT-6 Luna with reasoning set to none. Jev and the Decisions API run with their defaults. Times are measured from our server, so they include the network.
Synthetic cases show how a model behaves on work like yours; they don’t establish how it will perform in your business. What you run is sent to the providers to answer and isn’t stored by us. Privacy · Back to Labs
Bring one workflow to a free conversation, thirty to forty-five minutes. We’ll show you what could be automated, prepared for approval or left with your people.